Mofa Xingyun is a 3D digital human development platform with real-time driving, video generation, speech synthesis, and SDK or API integration options.
Mofa Xingyun: 3D Digital Human Platform
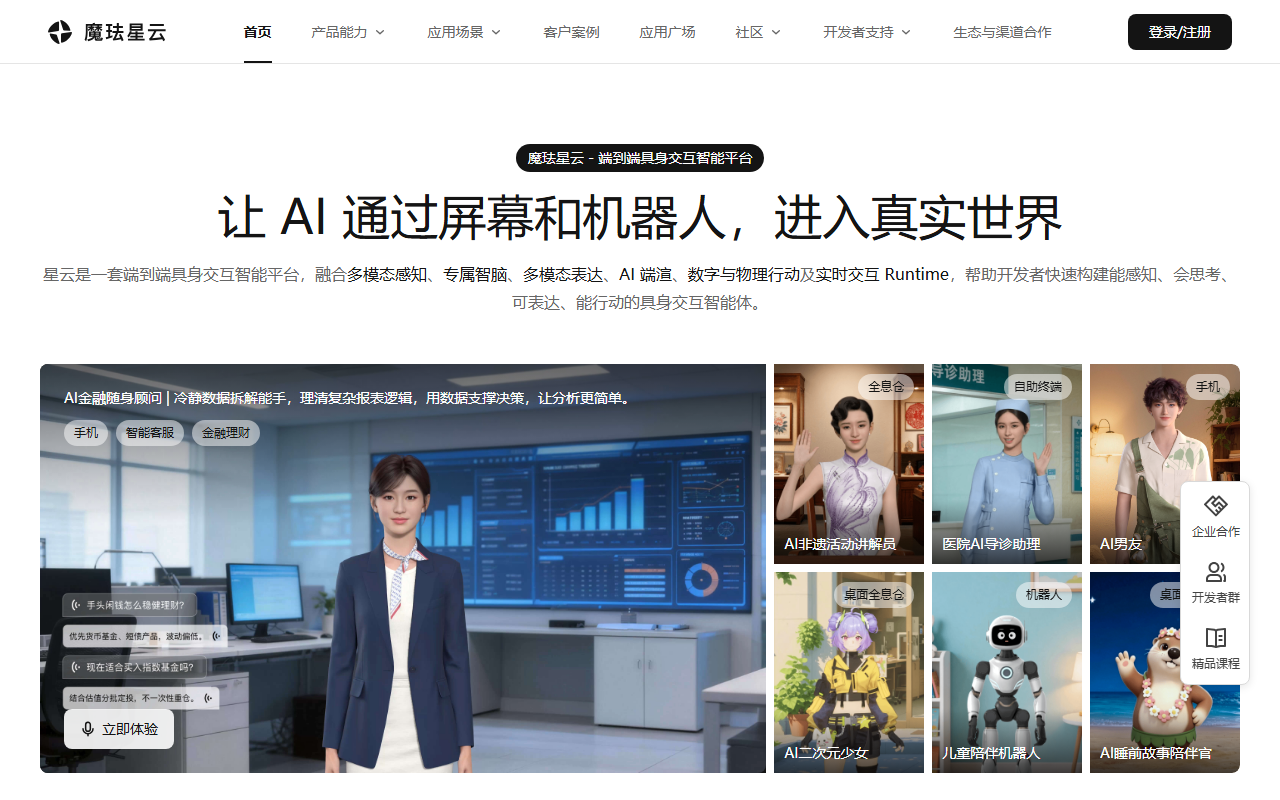
Mofa Xingyun is an open platform for developers building 3D digital humans. Product information describes text-driven real-time speech, facial expression, and movement, alongside video generation, speech synthesis, and multimodal interaction. Developers can connect these capabilities through an SDK or API according to their project needs. Available features, deployment requirements, and model capabilities should be verified in the current official documentation.
Core capabilities
- Real-time avatar driving: Generate a digital human’s speech, expressions, gaze, gestures, and body movements from text for interactive experiences.
- Digital human video: Product materials describe creating 3D presenter videos from text or PPT, including automated scene setup, lighting, and camera movement.
- Speech synthesis: Multilingual voices and expressive delivery are described. Voice cloning is also mentioned; obtain the speaker’s explicit authorization before using a cloned voice.
- Multimodal interaction: Combine text meaning and emotion with generated speech and movement.
- Developer integration: The described options include an embodied-driving SDK, a video-generation API, and a speech-synthesis API.
Getting started
- Visit the Mofa Xingyun website to review product details, developer documentation, privacy terms, and current pricing.
- Register and create an application, then select real-time driving, video generation, or speech synthesis for your use case.
- Integrate the SDK or API according to the documentation and test latency, rendering, voice quality, and device behavior before launch.
- Before deployment, confirm data handling, user notice, rights to likenesses and voices, content review, and budget.
Billing and use cases
The platform is described as using credits, with different consumption for real-time driving, video generation, and speech synthesis. Video usage may depend on resolution, scene complexity, frame rate, and duration. Any published credit examples may change; check the live platform before generating content.
Potential applications include virtual customer service, digital instructors, on-screen presenters, interactive terminals, and sales training. Actual performance depends on content, configuration, connectivity, and endpoint devices. Confirm cross-device support, concurrency, latency targets, and commercial permissions through current documentation and project testing. For real-person likenesses or voices, obtain permission and follow privacy and applicable legal requirements.
FAQs
What can it generate?
The product description covers real-time speech, expressions, and movement, videos from text or PPT, and multilingual speech synthesis.
Are developer APIs available?
The materials list an embodied-driving SDK, video-generation API, and speech-synthesis API. Current access and requirements are in official developer documentation.
How is usage charged?
The platform is described as credit-based, with consumption varying by feature and video settings. Confirm current rates and expected usage before running a job.
Frequently asked questions
What can Mofa Xingyun do?
The product information describes real-time speech, expressions, and motion, video generation from text or PPT, and multilingual speech synthesis.
How can developers integrate it?
The material describes a real-time driving SDK, video generation API, and speech synthesis API. Check official documentation for current access and requirements.
How is it billed?
The platform is described as credit-based. Rates can vary by feature and video settings, so confirm current pricing before generation.